The scores in every model launch are real measurements of something — but contamination, saturation, and the gap between test performance and your Tuesday afternoon are why numbers alone never settle it.
Every serious AI release ships with a documentation page — and its benchmark table, limitations list, and safety section tell you more than any launch event, if you know which parts are load-bearing.
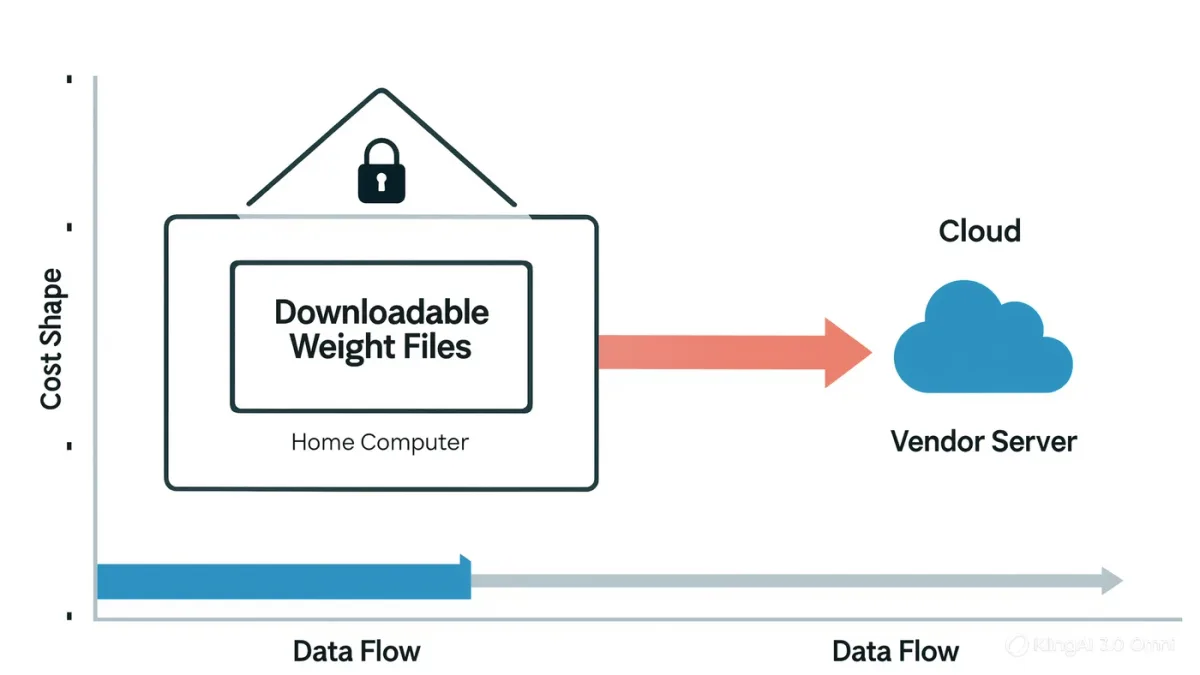
"Open" in AI has a specific meaning — downloadable weights you can run yourself — and it splits the industry into two very different bargains about cost, control, and who sees your prompts.
Model names look like part numbers but encode real information — family, generation, and tier — and knowing the three layers tells you which model to pick before you ever read a benchmark.